Mapping Player Decision Trees in Roulette Apps Using Historical Odds Data from Free Play Sessions
Geschrieben von Casey Washington · 18.10.2026
Mapping Player Decision Trees in Roulette Apps Using Historical Odds Data from Free Play Sessions
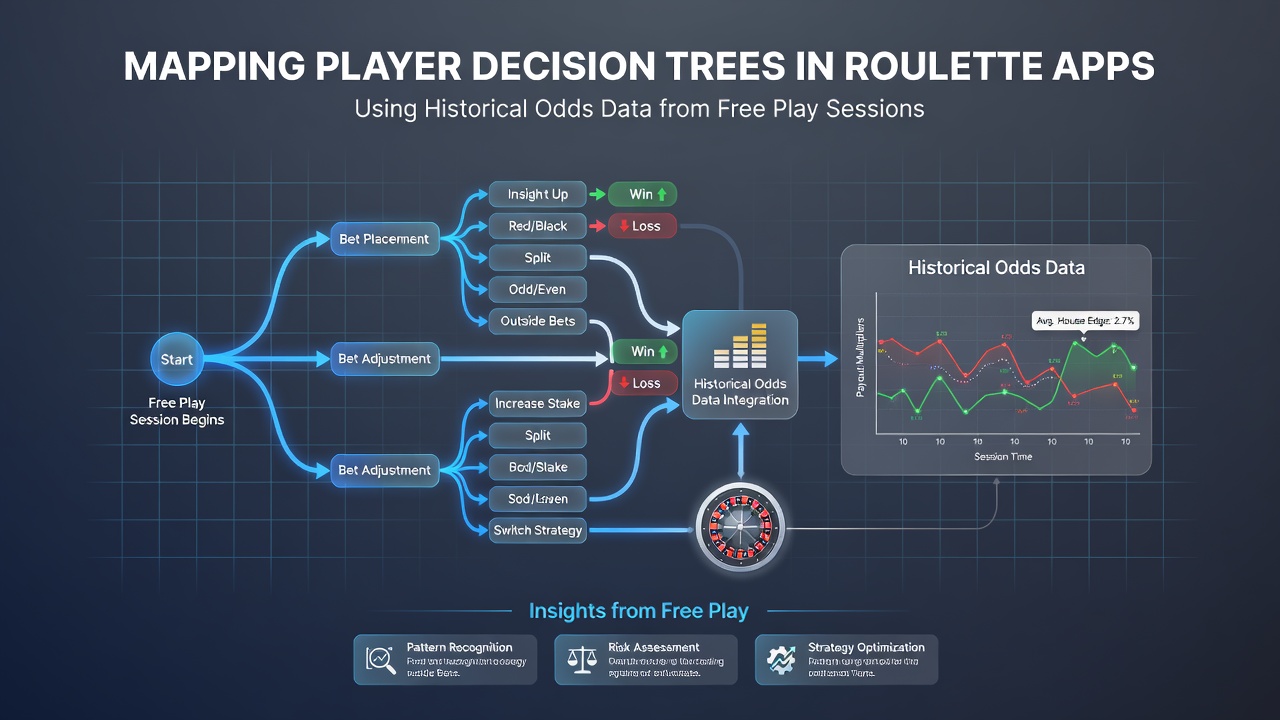
Analysts in the digital gaming sector have turned to decision tree mapping as a way to organize player choices in roulette applications, and this approach draws directly from historical odds data gathered during free play sessions where participants test strategies without financial stakes involved. Data sets from these sessions reveal sequences of bets, color selections, and number groupings that repeat across large user bases, while the underlying odds from past spins provide the context that shapes those sequences over extended periods.
Collecting and Structuring Free Play Data
Free play environments in roulette apps generate extensive logs that record every wheel spin outcome alongside the exact bets placed by users at each step, and researchers compile these logs into structured formats suitable for algorithmic processing. The process starts with timestamped records that include bet amounts, chosen numbers or sections, and the resulting payouts or losses, then continues with the integration of historical odds tables that show probability distributions for different wheel configurations. Teams working on these projects often segment the data by user session length and frequency of play, which allows patterns such as repeated shifts from even-money bets to column bets to surface clearly when the data undergoes clustering analysis.
October 2026 saw several development teams release updated tools that incorporate real-time filtering of free play records, and these updates align with broader industry efforts to standardize data formats across multiple app platforms. Observers note that the volume of available sessions has grown steadily, creating datasets that contain millions of individual decisions suitable for training machine learning models.
Building Decision Trees from Odds Histories
Decision tree construction begins when algorithms sort player actions according to the odds that preceded each choice, and this sorting produces branches that represent common pathways such as moving from red-black bets to dozen bets after a sequence of losses. Each node in the tree captures a specific decision point, while the branches extend based on the frequency with which users followed one option over another given the same historical odds context. The resulting structures highlight how certain odds thresholds trigger consistent shifts in betting behavior across diverse user groups.
One research group applied these methods to data from multiple European and North American apps and found that players tended to increase bet size after three consecutive spins landing outside a chosen dozen when the historical odds for that dozen remained above 32 percent. Such findings emerge only after the trees undergo pruning to remove low-frequency branches, which leaves the dominant patterns intact for further examination.
Integration with Live App Features
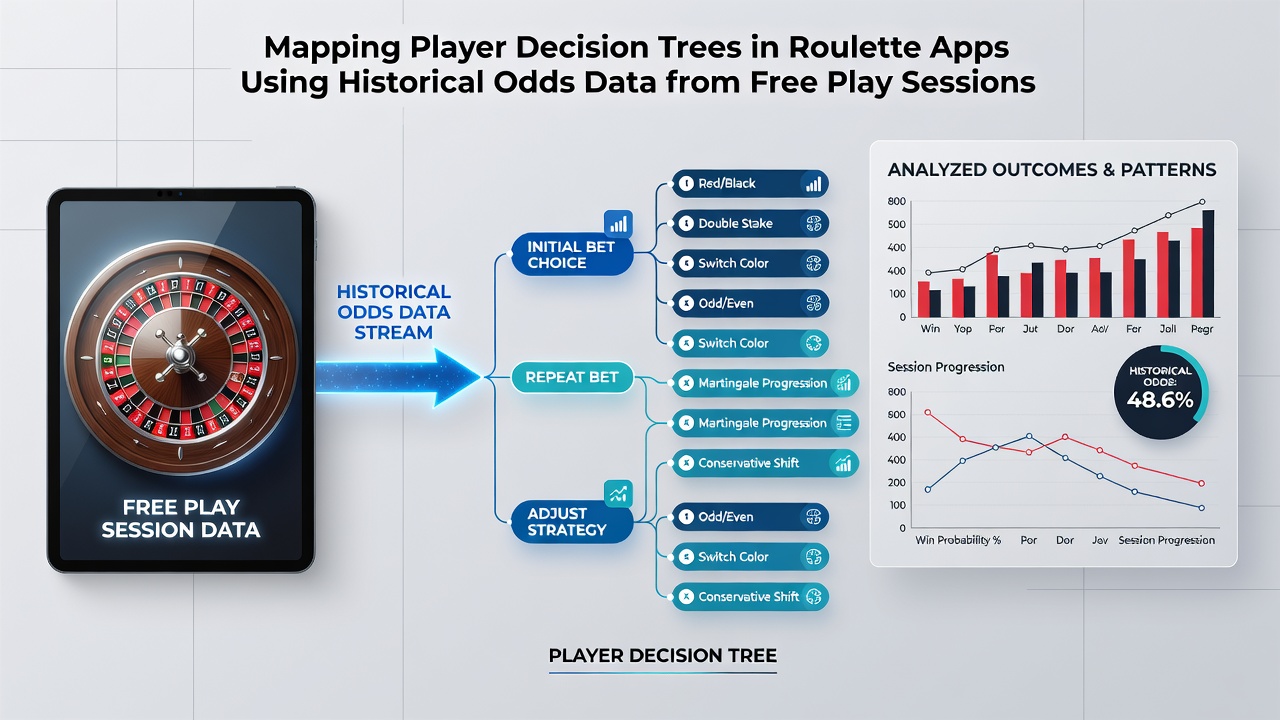
App developers incorporate the mapped trees into training modules that present users with simulated scenarios drawn from historical odds, and these modules allow players to observe how their own decision sequences compare against aggregated patterns. The integration occurs through backend systems that reference the trees in real time, adjusting suggested practice spins to match the probability distributions recorded in the original free play datasets. Several platforms now display simplified versions of the trees to users so that individuals can trace their recent choices back to the most common branches identified in the broader data.
According to figures released by the Nevada Gaming Control Board, free play features within regulated apps continue to account for a measurable share of user engagement metrics, and this engagement supplies the raw material for ongoing tree refinement. Meanwhile reports from the Australian Gambling Research Centre indicate similar growth in session volumes within that region, supporting cross-market comparisons of decision pathways.
Analytical Techniques and Validation Steps
Validation of the trees relies on hold-out testing where portions of the free play data remain unseen during initial construction, and then the model predicts subsequent choices with measurable accuracy rates. Techniques such as entropy calculation help determine which odds variables split the data most effectively, while cross-validation across different app versions confirms that the core structures remain stable despite interface changes. Analysts also track how external factors like session duration alter branch probabilities, producing conditional trees that account for fatigue or extended play effects.
Those who have examined these models note that certain branches appear consistently across datasets collected months apart, suggesting stable behavioral tendencies that persist even as new users enter the apps. The trees therefore serve both descriptive and predictive roles when applied to new free play records.
Conclusion
Mapping player decision trees through historical odds data from free play sessions provides a systematic record of how users interact with roulette applications over time. The method combines large-scale data collection, algorithmic structuring, and iterative validation to produce representations that reflect actual choice patterns without requiring real-money transactions. Continued refinement of these trees supports both app feature development and broader analysis of digital gaming behaviors across regions.